4 Immediate Fixes Security Teams Need for Vector Database Security
4 Immediate Fixes Security Teams Need for Vector Database Security
Treat every vector index as a production-sensitive data store, not a caching layer. That means storage-bound isolation between tenants, least-privilege access for every service identity, and lifecycle governance that follows embeddings into caches, evaluation sets, and backups. The standards behind this are not theoretical: NIST’s Zero Trust guidance and OWASP’s LLM security project both point the same direction, and this kind of approach is recommended for secure retrieval pipelines.
TL;DR:
- Encryption at rest does not prevent retrieval-time attacks; securing access controls, isolation, and audit logs is essential for protection.
- Implementing distance-preserving encryption schemes like DCPE can mitigate inversion risks but may introduce accuracy and latency trade-offs.
- Maintaining a detailed AI-BOM that tracks data sources, model versions, and access is critical for effective data lifecycle management and incident response.
- Using scoped, per-service identities and storage-bound tenant isolation minimizes the risk of cross-tenant leakage and credential misuse.
- Publicly accessible vector databases with no authentication remain a common but preventable exposure risk.
Table of Contents
- Why Vector Databases Are a Distinct Security Problem
- Secure-by-Design Data Lifecycle for Embeddings
- Access Control and Identity: Least Privilege for Vector Workloads
- Why Standard Encryption Isn’t Enough for Embeddings
- Infrastructure Hardening: Network, Keys, and Backups
- Logging, Monitoring, and Incident Response for Vector Workloads
- Governance and Compliance: Making Vector Data Auditable
- A Prioritized Hardening Checklist for Security Teams
- What Practitioner Experience Looks Like in the Field
- What Teams Actually Need to Change
- Getting Expert Help Securing Your Vector Deployments
- Sources
- FAQ
Why Vector Databases Are a Distinct Security Problem
Vector database security differs from ordinary database security because the sensitive content isn’t stored as text. It’s stored as a numeric fingerprint of that text, and fingerprints turn out to be far more reversible than most engineering teams assume.
Embedding inversion is the process of reconstructing the original input from its vector representation. Research on models like Vec2Text has shown that embeddings can be reconstructed into original text with high fidelity in certain settings, especially with short sequences. Membership inference is a related attack where an adversary determines whether a specific record was part of the training or indexed set, without ever recovering the full text. PoisonedRAG describes attacks where a malicious actor injects crafted documents into a retrieval-augmented generation pipeline so the model returns manipulated or harmful content on legitimate queries.
Here’s the part most security teams miss: encryption at rest does nothing to stop any of these attacks, because the leakage happens at retrieval time, through queries an authorized application is allowed to make. A well-behaved similarity search that returns the nearest neighbors to a query vector is functioning exactly as designed. The problem is that “as designed” can still expose sensitive patient notes, proprietary contracts, or personal identifiers to a user who should never see them.
Real-world exposure has followed a predictable pattern:
- Security scans have found publicly reachable vector database instances with no authentication configured at all.
- Metadata-filter-only isolation has caused cross-tenant leakage when filters were misapplied or bypassed.
- Coarse, long-lived API keys have given entire applications access to indexes they only needed to read from partially.
Secure-by-Design Data Lifecycle for Embeddings
Governance has to travel with the data, and vector data multiplies fast. One document can spawn dozens of chunks, several embedding versions, a cached query result, and a copy in a backup snapshot. If your retention policy only touches the original document, you’ve left five other copies exposed.
Build the lifecycle in this order:
- Classify before you embed. Tag source documents by sensitivity (public, internal, restricted, regulated) before they ever reach an embedding model, and strip or mask fields that don’t need to be searchable.
- Minimize what gets embedded. Don’t vectorize entire records when a summary or redacted excerpt would serve the retrieval use case just as well.
- Maintain an AI-BOM. Keep a living inventory that maps each index to its source data, the embedding model version used, and every downstream application that queries it. This single artifact is what lets an incident responder answer “what else is affected” in minutes instead of days, an approach Safeguard’s security research recommends for exactly this reason.
- Propagate deletion everywhere. When a record is deleted or a user exercises a right-to-erasure request, that deletion needs to reach the vector index, any query cache, evaluation datasets, and backup snapshots, not just the source database.
Pro Tip: Build your AI-BOM in a spreadsheet or lightweight database before you build anything fancier. The value comes from having the map, not from the tooling that displays it.
Access Control and Identity: Least Privilege for Vector Workloads
Most vector database breaches trace back to identity problems, not cryptographic ones. A service account with more scope than it needs is the single most common failure mode security teams encounter when they audit a RAG pipeline.
Start with per-service identities. Every application, every microservice, and every scheduled job that touches a vector index should authenticate with its own scoped credential, tied into your existing OIDC or IAM provider rather than a shared static key. From there, layer on role-based, attribute-based, or context-based access control (RBAC, ABAC, or CBAC) so that a service reading embeddings for a customer support bot can’t also write to the index used for financial risk scoring.
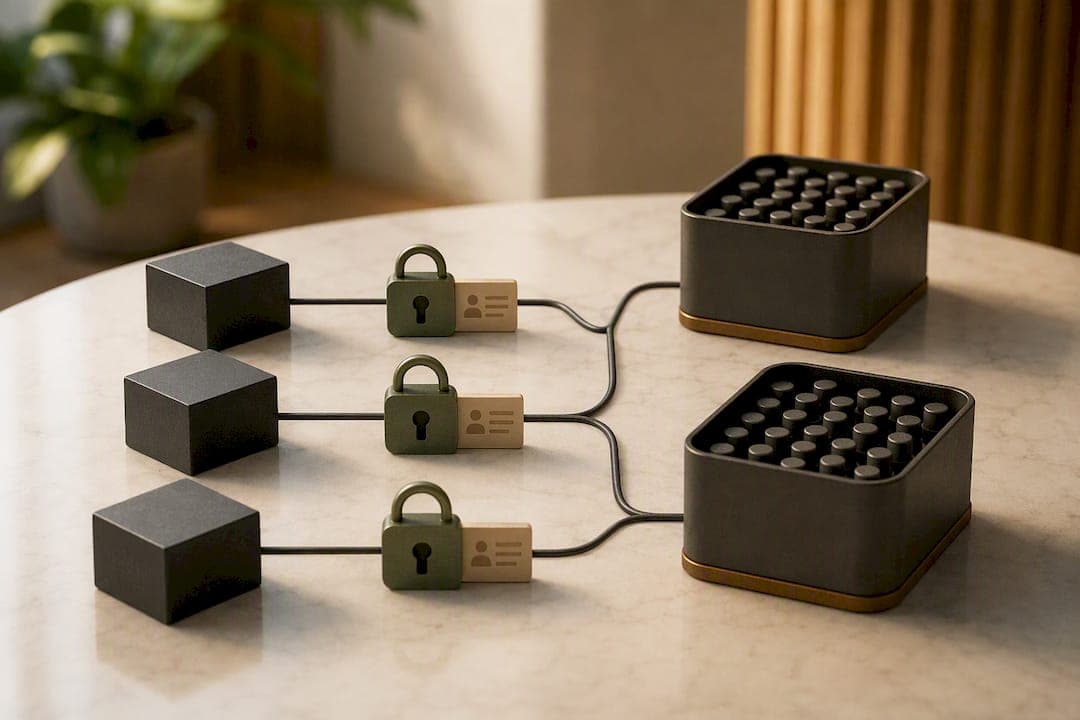
Isolation architecture matters just as much as identity. Metadata-filter isolation, where every tenant’s vectors sit in one shared index and a filter field decides what’s returned, is convenient but fragile. A single missed filter, a bug in query construction, or a compromised credential exposes every tenant at once. Storage-bound isolation, using separate namespaces, collections, or physical indexes per tenant, contains that blast radius by design.
A few non-negotiables round this out:
- Rotate API keys on a fixed schedule, not “whenever someone remembers.”
- Store secrets in a dedicated secrets manager, never in environment files or config repos.
- Audit every credential quarterly and revoke anything unused for more than 90 days.
- Require short-lived tokens over long-lived API keys wherever your vector database vendor supports them.
Why Standard Encryption Isn’t Enough for Embeddings
Here’s the tension nobody likes to talk about: traditional encryption and similarity search are structurally at odds. Similarity search works because nearby vectors in the embedding space represent semantically related content. Standard AES-style encryption scrambles that structure completely; encrypt two similar vectors and their encrypted forms have no meaningful distance relationship anymore. You end up with data that’s secure and useless at the same time.
This is why the industry is converging on distance-comparison-preserving encryption (DCPE), sometimes discussed alongside broader property-preserving encryption (PPE) approaches. DCPE preserves the relative distances between vectors closely enough to support approximate nearest-neighbor search, while making direct inversion of any single vector substantially harder. IBM’s implementation research shows this works with a configurable approximation factor, trading a small, measurable accuracy loss for real protection against reconstruction attacks.
That trade-off is the catch. DCPE and similar schemes introduce latency overhead and recall degradation that varies by dataset and configuration. The sensible adoption path is a pilot: run DCPE against a non-production index, measure the recall drop against your actual service-level agreement, and only promote it to production once you know the real cost.
Beyond encryption schemes, a few operational habits reduce exposure regardless of which cryptographic approach you pick:
- Reduce what gets encoded in the first place. Strip identifiers, account numbers, and free-text PII before embedding rather than trying to protect them after the fact.
- Apply tenant-scoped keys so a compromised key exposes one tenant’s vectors, not the whole index.
- Re-embed after every model version change. Indexes built on a deprecated embedding model carry compatibility and security debt that compounds over time, which is exactly why the AI-BOM has to track model version alongside source data.
Pro Tip: If your team hasn’t tested what an inversion attack recovers from your own embeddings, budget a week for it before you evaluate DCPE. You need a baseline to know if the mitigation actually helped.
Infrastructure Hardening: Network, Keys, and Backups
A shocking number of vector database exposures never involve a sophisticated attack at all. They involve a port that should never have been open to the internet in the first place.
Vector databases and their management consoles should never sit on public IP addresses. Bind them to private networks, require a VPN or proxy layer for any external access, and treat a publicly reachable vector store the same way you’d treat a publicly reachable production SQL database: as an incident waiting to happen. Repeated scans have turned up exposed vector database instances with no authentication layer sitting in plain view.
Layer in these controls next:
- Enforce TLS on every client connection, and add mutual TLS (mTLS) for service-to-service traffic within your infrastructure so compromised internal traffic can’t spoof a trusted caller.
- Use a cloud key management service or hardware security module for the full key lifecycle, generation, rotation, and revocation, rather than managing keys by hand. Azure’s encryption guidance and AWS’s vector storage documentation both detail how KMS integration and server-side encryption defaults apply specifically to vector indexes and their metadata.
- Encrypt backups and snapshots with the same rigor as the live index. A snapshot sitting in unencrypted cold storage is still a full copy of your sensitive embeddings.
- Note that some cloud vector services lock encryption settings at creation time for a given bucket or index. Decide on your key management approach before provisioning, not after.
Logging, Monitoring, and Incident Response for Vector Workloads
You can’t investigate what you never logged, and generic application logging misses almost everything that matters for a vector store.
- Log every query with full context. Capture the requesting identity, the exact filter predicates applied, the top-k value requested, the identifiers returned, and a timestamp. Vague logs like “user queried index X” are worthless for forensics; you need the filter and the result set, which is what makes audit logs useful for both DSAR requests and incident response.
- Set anomaly baselines. Flag unusually high-rate retrievals from a single identity, queries that request an abnormally wide top-k, or any query pattern that crosses tenant boundaries it shouldn’t touch.
- Run red-team exercises on your own pipeline. Test embedding inversion against your actual production vectors and attempt a poisoning injection against your retrieval flow before an adversary does it for you.
- Maintain a patch SLA. Track CVEs and vendor advisories for your vector database and embedding libraries, and commit to a fixed remediation window, not “we’ll get to it next sprint.”
Governance and Compliance: Making Vector Data Auditable
Regulators and auditors don’t care that your sensitive data is stored as floating-point numbers instead of plain text. If the original record was regulated, its embedding is too.
Label every embedding by the sensitivity classification of its source data, and carry that label into every derived copy, cache, and evaluation set it touches. This is the same asset-labeling discipline Zero Trust data security frameworks call for across any data lifecycle.
Data subject access requests can’t stop at the source database. A workflow that deletes a customer’s record from your primary system but leaves their embedding sitting in a vector index, a query cache, and last month’s backup hasn’t actually honored the request.
- Map every regulated data category to every index that contains its derivatives.
- Build DSAR workflows that reach embeddings, caches, and backups, not just source tables.
- Keep provenance records precise enough to answer “who queried this, and what did they see” for any given record, on demand.
Some AI consultancies build this kind of AI governance and compliance mapping directly into client engagements, because a governance policy that can’t reach the vector layer isn’t actually a complete policy.
A Prioritized Hardening Checklist for Security Teams
Not every control belongs on this week’s sprint board. Sequence matters.
Immediate (this week):
- Block public access to every vector database instance and management console.
- Enable TLS on all connections; add mTLS for service-to-service calls where supported.
- Rotate every API key and long-lived credential currently in use.
- Turn on query-level audit logging if it isn’t already running.
Medium term (this quarter):
- Move from metadata-filter isolation to storage-bound isolation for multi-tenant indexes.
- Replace shared credentials with per-service, scoped identities.
- Build the first version of your AI-BOM, mapping indexes to sources and consuming apps.
Long term (this year):
- Pilot DCPE or a similar property-preserving encryption approach on a non-production index.
- Automate DSAR propagation so deletion requests reach embeddings and backups automatically.
- Integrate embedding governance checks into your CI/CD pipeline so new indexes launch compliant by default.
| Timeframe | Primary risk addressed | Owner |
|---|---|---|
| Immediate | External exposure, credential misuse | Security engineering |
| Medium term | Cross-tenant leakage, unscoped access | Platform / SRE team |
| Long term | Inversion risk, compliance drift | AI governance lead |
What Practitioner Experience Looks Like in the Field
Some AI consultancies work inside client operations to build these controls into production AI systems, not bolt them on afterward. That means access control, tenant isolation, and provenance mapping get designed alongside the vector database architecture itself, whether the deployment sits in a hospital’s clinical record system or a logistics company’s routing engine. Teams that own their AI infrastructure, rather than depending on a vendor black box, can see and fix these gaps directly. That ownership model is the practical foundation behind every recommendation in this article.
What Teams Actually Need to Change
The biggest gap isn’t technical, it’s organizational. Security teams treat vector stores as an ML infrastructure concern, and ML teams treat them as a security concern, and the seam between the two is where breaches happen. Pair a security engineer with every RAG project from day one, name a single owner for the AI-BOM, and set a KPI for embedding-data risk that someone actually reports on. Schedule red-team retrieval tests quarterly, not once at launch.
— arosplatforms team
Getting Expert Help Securing Your Vector Deployments
Most teams don’t lack the will to secure their vector infrastructure. They lack the time to inventory every index, test every inversion path, and build governance that survives a compliance audit while still shipping features. Some AI consultancies help close that gap directly, running security assessments against actual retrieval pipelines, executing red-team inversion and poisoning tests, and building the AI-BOM and governance program compliance teams can use. Such engagements typically produce a full data and index inventory, a prioritized hardening plan sequenced like the checklist above, and a red-team findings report a security lead can act on immediately. If you’re building or scaling a retrieval system and want a second set of eyes on it before an auditor or an attacker finds the gaps first, start by exploring what an AI operating system built with security embedded from day one actually looks like for your industry.
Sources
- Protecting AI embedding vectors by using approximate distance preserving encryption for RAG applications
- Zero-Trust data security guide (CIO.gov / CISA)
- Text Embeddings Reveal (Almost) As Much As Text
- Amazon S3 Vectors data encryption and key management
FAQ
Who owns vector database security?
Ownership typically splits between security engineering, which handles access control and infrastructure, and the AI or ML team, which owns the embedding pipeline and model lifecycle. The safest setups assign a single named owner for the AI-BOM so no gap falls between the two teams.
What makes a vector database secure?
A secure vector database combines storage-bound tenant isolation, scoped least-privilege identities, encrypted transport and storage with proper key management, and full query-level audit logging. No single control does the job alone; OWASP’s LLM guidance frames this as a layered set of retrieval and isolation protections.
Is a vector database a NoSQL database?
Most vector databases share architectural traits with NoSQL systems, storing data as high-dimensional arrays rather than relational tables, but they’re purpose-built for similarity search rather than general document or key-value storage. The security implications differ too, since similarity search creates the retrieval-time leakage risk that standard NoSQL databases don’t face in the same way.
Does encryption alone protect a vector database?
No. Encryption at rest protects against someone stealing the raw files, but it does nothing to stop retrieval-time leakage through authorized queries, which is the more common real-world exposure path. Effective vector data protection requires access control, isolation, and monitoring layered on top of encryption, not instead of it.
How does embedding inversion actually work?
Embedding inversion trains a model to reverse-map a vector back toward the text that produced it, and research has shown this can recover original text with high fidelity in certain conditions, particularly with shorter inputs. That’s why security teams increasingly treat raw embeddings as sensitive data equivalent to the source text itself.